Repository navigation
[Bug]: Watermark age for PeriodicImpulse regression in v2.74.0 #39026
Description

What happened?
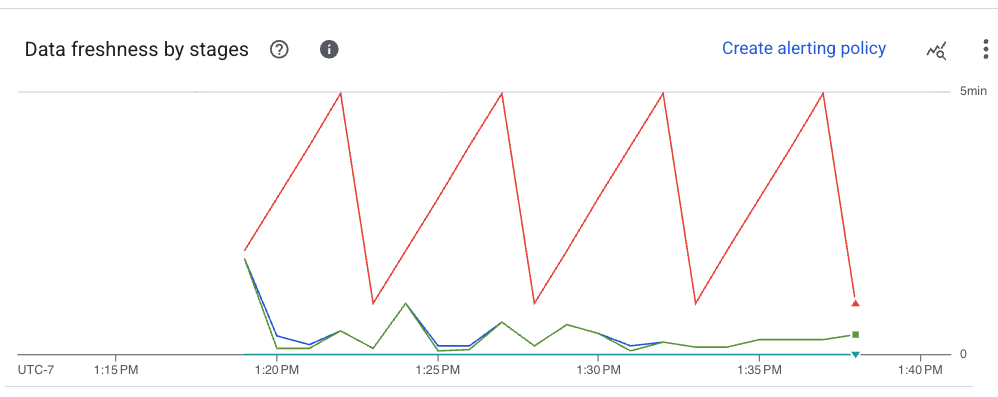
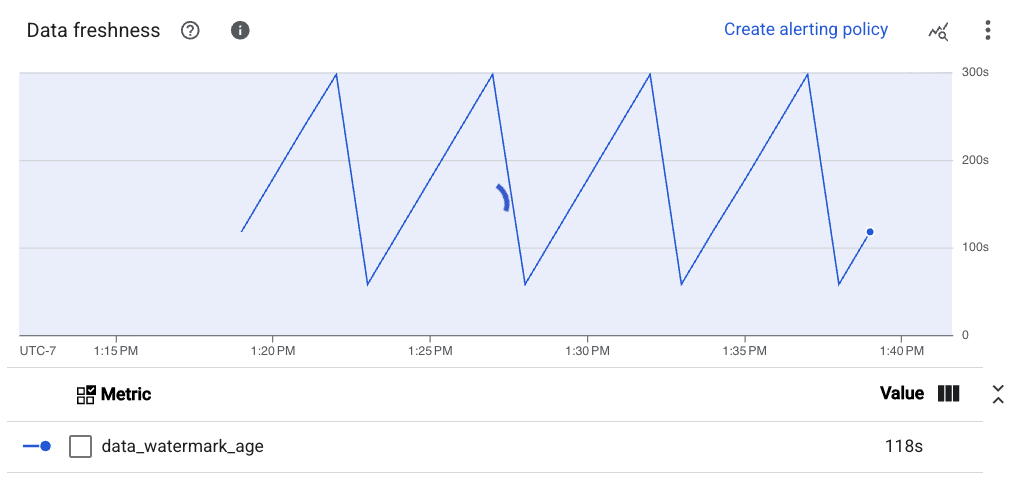
We noticed this after upgrading from v2.66.0 to v2.74.0 for our python sdk dataflow runner streaming jobs. We use side inputs from a PeriodicImpulse that fire at intervals that are longer than our streaming PCollection windows. With the upgrade to v2.74.0 the dataflow streaming job's reported watermark age for the stage with the side inputs and the overall job's watermark age now follows the side input periodic impulses' interval.
So if we have a side input that fires every hour, the job's watermark will have a saw tooth pattern climbing up to 1hour, when previously this didn't happen. The issue we are having is that we have alerts based on the job's watermark age which would now follow the periodic impulse with the longest firing interval.
To reproduce this I created a minimal example below to run with the dataflow runner with both v2.66.0 and v2.74.0 and I'm showing screenshots of the data freshness reported by dataflow:
Setup
Create a pubsub topic
gcloud pubsub topics create periodicimpulse-watermark --project=<project>Run the following script to publish messages:
#!/bin/bash
while true; do
    gcloud pubsub topics publish projects/<project>/topics/periodicimpulse-watermark \
        --message="Hello!" --project=<project>
    sleep 1
done
Created the following python sdk pipeline to submit with a side input with a periodic impulse firing every 300s:
import argparse
import time
import logging

import apache_beam as beam
from apache_beam.io.gcp.pubsub import ReadFromPubSub
from apache_beam.options.pipeline_options import PipelineOptions, StandardOptions
from apache_beam.transforms.periodicsequence import PeriodicImpulse
from apache_beam.transforms.trigger import AccumulationMode, AfterCount, AfterProcessingTime, Repeatedly
from apache_beam.transforms.window import GlobalWindows

PUBSUB_TOPIC = "projects/my-project/topics/periodicimpulse-watermark"
SIDE_INPUT_INTERVAL = 300


class JoinWithSideInput(beam.DoFn):
    def process(
        self,
        element,
        side_values=beam.DoFn.SideInputParam,
    ):
        processing_time = time.time()
        event_time = element.publish_time.timestamp()

        yield {
            "message_id": element.message_id,
            "event_time": int(event_time),
            "processing_time": int(processing_time),
            "side_input_time": int(list(side_values)[0]) if side_values else None,
        }


def run(argv=None):
    parser = argparse.ArgumentParser()
    parser.add_argument(
        "--output_table",
        required=True,
        help="BigQuery table to write results to, e.g. project:dataset.table",
    )
    known_args, pipeline_argv = parser.parse_known_args(argv)
    output_table = known_args.output_table

    options = PipelineOptions(pipeline_argv)
    options.view_as(StandardOptions).streaming = True

    schema = {
        "fields": [
            {"name": "message_id", "type": "STRING"},
            {"name": "event_time", "type": "INTEGER"},
            {"name": "processing_time", "type": "INTEGER"},
            {"name": "side_input_time", "type": "INTEGER"},
        ]
    }

    with beam.Pipeline(options=options) as p:
        side_input_pcol = (
            p
            | "SideInputImpulse" >> PeriodicImpulse(
                fire_interval=SIDE_INPUT_INTERVAL
            )
            | "SideInputWindow" >> beam.WindowInto(
                GlobalWindows(),
                trigger=Repeatedly(AfterCount(1)),
                accumulation_mode=AccumulationMode.DISCARDING,
            )
        )
        results = (
            p
            | "ReadPubSub" >> ReadFromPubSub(topic=PUBSUB_TOPIC, with_attributes=True)
            | "MainWindow" >> beam.WindowInto(
                GlobalWindows(),
                trigger=Repeatedly(AfterProcessingTime(10)),
                accumulation_mode=AccumulationMode.DISCARDING,
            )
            | "JoinWithSideInput" >> beam.ParDo(
                JoinWithSideInput(),
                side_values=beam.pvalue.AsIter(side_input_pcol),
            )
        )

        results | "WriteToBQ" >> beam.io.WriteToBigQuery(
            table=output_table,
            schema=schema,
            create_disposition=beam.io.BigQueryDisposition.CREATE_IF_NEEDED,
            write_disposition=beam.io.BigQueryDisposition.WRITE_APPEND,
            method=beam.io.WriteToBigQuery.Method.STREAMING_INSERTS,
        )


if __name__ == "__main__":
    logging.getLogger().setLevel(logging.INFO)
    run()
Submitting dataflow jobs
Submit with apache-beam v2.74.0
python periodic_impulse_watermark.py \
  --project=<project> \
  --job_name=periodicimpulse-beam-274 \
  --region=<region> \
  --runner=DataflowRunner \
  --temp_location=gs://<bucket>/temp \
  --output_table=<project>:<dataset>.periodic_impulse_watermark_v2_74
and submit another job with apache-beam v2.66.0
python periodic_impulse_watermark.py \
  --project=<project> \
  --job_name=periodicimpulse-beam-266 \
  --region=<region> \
  --runner=DataflowRunner \
  --temp_location=gs://<bucket>/temp \
  --output_table=<project>:<dataset>.periodic_impulse_watermark_v2_66
Result
Both jobs successfully write to their BigQuery tables. The difference is in the job's watermark age reported on dataflow.
v2.74.0
The watermark age is a sawtooth climbing to the 300s of the periodic impulse:
The same with the job's watermark age:
v2.66.0
There is no sawtooth pattern:


Issue Priority
Priority: 2 (default / most bugs should be filed as P2)
Issue Components
- Component: Python SDK
- Component: Java SDK
- Component: Go SDK
- Component: Typescript SDK
- Component: IO connector
- Component: Beam YAML
- Component: Beam examples
- Component: Beam playground
- Component: Beam katas
- Component: Website
- Component: Infrastructure
- Component: Spark Runner
- Component: Flink Runner
- Component: Prism Runner
- Component: Twister2 Runner
- Component: Hazelcast Jet Runner
- Component: Google Cloud Dataflow Runner
Activity
Abacn commentedon Jul 24, 2026
Thanks for reporting this issue. Would it be possible to narrow down the version that introduced this regression. 2.66.0 to 2.74.0 still has a few intermediate versions
Edit: checked history that last Python periodic impulse change happened in #35569, for Beam 2.67.0. If Beam 2.67.0 already shows this watermark change, it's likely the causeEdit: actually due to #35412 (in Beam 2.67.0). I'm able to reproduce the watermark pattern in Beam 2.67.0
Note that the orange line is the step of PeriodicImpulse output. Plus, the "overall" watermark is the minimum timestamp of all. It's more a visual effect. The downstream (BigQuery write, etc) watermark (can be shown in other lines in your screenshot) isn't affected, which would control when window gets fired. There fore this is more a visual effect and not affecting semantics of downstream main input branch.
Abacn commentedon Jul 24, 2026
cc: @shunping
jbandoro commentedon Jul 27, 2026
Thank you for the update and taking the time to reproduce.
The reason why I raised this issue was because the dataflow job metric,
dataflow.googleapis.com/job/data_watermark_age, now is tracking the periodic impulse because I believe this metric reports the max watermark age of data that is awaiting processing. Since our streaming job writes to many different bigquery sinks, having the single job metric was helpful for monitoring and alerting. But upgrading to v2.67.0+ breaks the monitoring/alerting since the job's watermark age is now representative of the periodic impulse.Fix PeriodicImpulse/PeriodicSequence watermark regression (#39026) (#…
shunping commentedon Aug 19, 2026
Thanks for fixing this!
I agree with @Abacn that this is primarily a visual effect of how the freshness is calculated and shown in the chart. It seems that setting the watermark estimator to a future timestamp when the defer path is reached results in a flat freshness chart (i.e., freshness is zero because the estimator is ahead of the current timestamp).