diff --git a/assets/architecture.svg b/assets/architecture.svg
new file mode 100644
index 0000000..a5801cf
--- /dev/null
+++ b/assets/architecture.svg
@@ -0,0 +1,62 @@
+
diff --git a/src/autograd/anomaly.rs b/src/autograd/anomaly.rs
index 3569f03..73cfabf 100644
--- a/src/autograd/anomaly.rs
+++ b/src/autograd/anomaly.rs
@@ -16,6 +16,12 @@ pub fn is_detecting() -> bool {
}
/// Run `f` with gradient checking on.
+///
+/// ```
+/// # use fastnn::prelude::*;
+/// let w = Param::new(Tensor::from_vec(vec![1.0, 2.0], &[2]));
+/// detect_anomaly(|| w.tensor().exp().sum().backward());
+/// ```
pub fn detect_anomaly(f: impl FnOnce() -> T) -> T {
let _guard = Enabled::new();
f()
diff --git a/src/autograd/mod.rs b/src/autograd/mod.rs
index 401d553..093609c 100644
--- a/src/autograd/mod.rs
+++ b/src/autograd/mod.rs
@@ -1,5 +1,26 @@
//! Reverse-mode autodiff. Each differentiable tensor carries a [`Node`] with its
//! backward rule and inputs, so the graph is just the tensors and there is no tape.
+//!
+//! Weights live in [`Param`](crate::nn::Param) handles. Call `backward()` on a
+//! scalar and each handle's gradient slot fills in.
+//!
+//! ```
+//! use fastnn::prelude::*;
+//!
+//! let w = Param::new(Tensor::from_vec(vec![1.0, 2.0], &[2]));
+//! let loss = w.tensor().mul_scalar(3.0).sum();
+//! loss.backward();
+//! assert_eq!(w.grad().unwrap().to_vec(), vec![3.0, 3.0]);
+//! ```
+//!
+//! - [`no_grad`] runs a closure without building a graph. Use it for inference.
+//! - [`detect_anomaly`] panics at the first rule that produces a NaN or inf, naming it.
+//! - [`ops`] holds one backward rule per forward op, in files named like `tensor/ops`.
+//!
+//! A new op is a forward in `tensor/ops`, a rule in [`ops`] that returns gradients
+//! in input order and saves only detached tensors, and a case in
+//! `tests/gradcheck.rs`, which checks every rule against central finite differences
+//! of its own forward.
pub mod anomaly;
pub mod engine;
diff --git a/src/cuda/mod.rs b/src/cuda/mod.rs
index fa58403..6d17a0e 100644
--- a/src/cuda/mod.rs
+++ b/src/cuda/mod.rs
@@ -1,6 +1,15 @@
//! GPU layer: device setup, memory ([`buffer`]), raw bindings ([`ffi`]) and safe wrappers ([`kernels`]).
//!
-//! Without the `cuda` feature, `cuda/stubs.c` stands in for the kernels and [`device_count`] is 0.
+//! A training script never calls this module directly. Pick a device with
+//! [`Device::best`](crate::tensor::Device::best) or
+//! [`Device::cuda`](crate::tensor::Device::cuda) and move the model and the loader
+//! to it.
+//!
+//! Without the `cuda` feature, `cuda/stubs.c` stands in for the kernels and
+//! [`device_count`] is 0. With it, `build.rs` compiles `cuda/kernels.cu` with
+//! `nvcc`. Matmul goes through cuBLAS. The other kernels use fast math, so GPU
+//! results differ from the CPU in the last few digits, and `tests/cuda_parity.rs`
+//! checks each one against the CPU path.
pub mod buffer;
pub mod ffi;
diff --git a/src/data/mod.rs b/src/data/mod.rs
index 2b6f322..ad66e96 100644
--- a/src/data/mod.rs
+++ b/src/data/mod.rs
@@ -1,4 +1,34 @@
//! Datasets, batching, and MNIST.
+//!
+//! A [`Dataset`] writes one item into a slice. A [`DataLoader`] fills one buffer
+//! per batch from it, shuffles, and can place batches on a device.
+//! [`TensorDataset`] wraps two tensors, and [`Mnist`] downloads the digits once
+//! and caches them.
+//!
+//! ```
+//! use fastnn::data::{DataLoader, Dataset};
+//!
+//! struct Squares;
+//!
+//! impl Dataset for Squares {
+//! fn len(&self) -> usize { 1000 }
+//! fn input_shape(&self) -> Vec { vec![1] }
+//! fn target_shape(&self) -> Vec { vec![1] }
+//! fn write(&self, i: usize, input: &mut [f32], target: &mut [f32]) {
+//! let x = i as f32 / 1000.0;
+//! input[0] = x;
+//! target[0] = x * x;
+//! }
+//! }
+//!
+//! let loader = DataLoader::new(&Squares, 100).shuffle(true);
+//! assert_eq!(loader.batches(), 10);
+//! for batch in loader.iter() {
+//! // A [1] item batches to [batch], like a label vector, not [batch, 1].
+//! assert_eq!(batch.inputs.shape(), &[100]);
+//! assert_eq!(batch.targets.shape(), &[100]);
+//! }
+//! ```
pub mod dataset;
pub mod loader;
diff --git a/src/lib.rs b/src/lib.rs
index 927979b..9d41359 100644
--- a/src/lib.rs
+++ b/src/lib.rs
@@ -1,6 +1,29 @@
//! # FastNN
//!
-//! A deep learning library in Rust with optional CUDA kernels.
+//! A robust deep learning library in Rust with CUDA kernels.
+//!
+//! FastNN trains neural networks in Rust. It has tensors with automatic
+//! differentiation, the layers and optimizers behind MLPs, CNNs, RNNs and
+//! transformers, data loading, and checkpoints a run can resume from. It runs on
+//! the CPU out of the box and on NVIDIA GPUs with the `cuda` feature.
+//!
+//! The whole stack is in this crate: Rust on the CPU, and with the `cuda`
+//! feature the kernels in the same repository. It is written to be read, so you
+//! can follow `loss.backward()` from your training loop down to the kernel.
+//! Every backward rule is tested against finite differences of its own forward,
+//! every CUDA kernel against the CPU path, and `unsafe` appears only in the
+//! CUDA bindings.
+//!
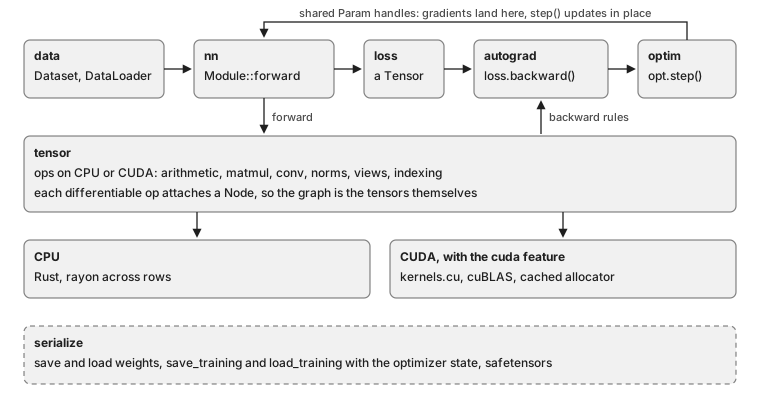
+//! 
+//!
+//! A batch goes through the model, the ops build a graph as they run, and the
+//! loss sits at its end. `backward()` walks that graph and leaves a gradient in
+//! each [`Param`](nn::Param). The optimizer holds the same `Param` handles, so
+//! `step()` reads the gradients and updates the weights in place.
+//!
+//! # Quick start
+//!
+//! Train a classifier on MNIST:
//!
//! ```no_run
//! use fastnn::prelude::*;
@@ -31,23 +54,371 @@
//! # }
//! ```
//!
-//! Modules: [`tensor`], [`autograd`], [`nn`], [`optim`], [`data`], [`serialize`], [`cuda`].
+//! The [examples] are complete programs. Run one with
+//! `cargo run --release --example `:
+//!
+//! | Example | What it shows |
+//! |---|---|
+//! | `simple_mlp` | MLP learning XOR, the smallest training loop |
+//! | `mnist_mlp` | Dataset download, batching, evaluation, checkpointing |
+//! | `mnist_cnn` | Convolutions, batch norm, pooling, an LR schedule |
+//! | `char_lm` | Small GPT trained from scratch, resumes after Ctrl-C |
+//! | `finetune` | Pretrain, freeze the backbone, train a new head |
+//! | `gan` | Two networks trained against each other |
+//! | `vae` | Variational autoencoder on 2-D data |
+//! | `reinforce` | Policy gradient on a bandit |
+//! | `multi_task` | Shared trunk, two heads, one combined loss |
+//!
+//! Use `--release`. Debug builds are about 50x slower.
+//!
+//! [examples]: https://github.com/CanReader/FastNN/tree/master/examples
+//!
+//! # A Tour of FastNN
+//!
+//! A training project meets the crate in a fixed order: build a model, train it,
+//! feed it data, save it, move it to a GPU, maybe generate from it, and debug it
+//! when a run goes bad. This tour follows that order and shows the API for each
+//! step. Everything a script needs is in the [`prelude`], and each module's own
+//! page goes deeper.
+//!
+//! ## Models
+//!
+//! A model is anything that implements [`Module`](nn::Module), and
+//! [`Sequential`](nn::Sequential) chains layers into one. A layer's weights are
+//! [`Param`](nn::Param) handles, shared with the optimizer, so training never has
+//! to borrow the model.
+//!
+//! ```
+//! use fastnn::prelude::*;
+//!
+//! let model = Sequential::new()
+//! .add(Linear::new(16, 32))
+//! .add(ReLU)
+//! .add(Dropout::new(0.1))
+//! .add(Linear::new(32, 4));
+//!
+//! let logits = model.forward(&Tensor::randn(&[8, 16]));
+//! assert_eq!(logits.shape(), &[8, 4]);
+//! assert_eq!(model.num_parameters(), 16 * 32 + 32 + 32 * 4 + 4);
+//! ```
+//!
+//! Your own layer needs `forward`, plus `named_parameters` if it has weights.
+//! Device placement, parameter counting and gradient zeroing follow from those.
+//!
+//! ```
+//! use fastnn::nn::module::scoped;
+//! use fastnn::prelude::*;
+//!
+//! struct Residual { inner: Linear }
+//!
+//! impl Module for Residual {
+//! fn forward(&self, x: &Tensor) -> Tensor {
+//! x.add(&self.inner.forward(x).relu())
+//! }
+//! fn named_parameters(&self) -> Vec<(String, Param)> {
+//! scoped("inner", self.inner.named_parameters())
+//! }
+//! }
+//! ```
+//!
+//! [`nn`] has the rest: convolutions with dilation and groups, pooling, batch,
+//! layer and RMS normalization, embeddings, LSTM and GRU, multi-head attention,
+//! and transformer encoder and decoder stacks.
+//!
+//! ## Training
+//!
+//! An optimizer takes the model's parameters and a learning rate. A
+//! [`LrSchedule`](optim::LrSchedule) maps the step to a rate, and `set_lr`
+//! applies it. The losses are plain functions in [`nn`].
+//!
+//! ```
+//! use fastnn::prelude::*;
+//!
+//! let model = Sequential::new().add(Linear::new(4, 3));
+//! let mut opt = AdamW::new(model.parameters(), 1e-3);
+//! let schedule = Warmup::new(CosineAnnealing::new(1e-3, 1000), 100);
+//!
+//! let x = Tensor::randn(&[8, 4]);
+//! let targets = [0, 1, 2, 0, 1, 2, 0, 1];
+//!
+//! for step in 0..3 {
+//! opt.set_lr(schedule.lr_at(step));
+//! let loss = cross_entropy(&model.forward(&x), &targets);
+//!
+//! opt.zero_grad();
+//! loss.backward();
+//! clip_grad_norm(opt.parameters(), 1.0);
+//! opt.step();
+//! }
+//! ```
+//!
+//! [`Dropout`](nn::Dropout) and [`BatchNorm2d`](nn::BatchNorm2d) behave
+//! differently at inference, so call `model.eval()` before validation and
+//! `model.train()` after.
+//!
+//! To fine-tune, freeze what should not move. A frozen parameter hands out a
+//! detached tensor, so the backward pass stops there and no gradient is computed
+//! for it at all. The optimizer skips a parameter with no gradient.
+//!
+//! ```
+//! # use fastnn::prelude::*;
+//! let backbone = Linear::new(16, 16);
+//! backbone.freeze();
+//!
+//! let model = Sequential::new().add(backbone).add(ReLU).add(Linear::new(16, 2));
+//! let mut opt = Adam::new(model.parameters(), 1e-3); // only the head will move
+//! ```
+//!
+//! [`optim`] has [`SGD`](optim::SGD), [`Adam`](optim::Adam),
+//! [`AdamW`](optim::AdamW), [`RMSprop`](optim::RMSprop),
+//! [`Adagrad`](optim::Adagrad), [`Adadelta`](optim::Adadelta),
+//! [`RAdam`](optim::RAdam) and [`Lion`](optim::Lion), the
+//! [`Lookahead`](optim::Lookahead) and [`Ema`](optim::Ema) wrappers, and the
+//! [`Warmup`](optim::Warmup), [`CosineAnnealing`](optim::CosineAnnealing),
+//! [`OneCycle`](optim::OneCycle) and [`StepDecay`](optim::StepDecay) schedules.
+//! [`CrossEntropyLoss`](nn::CrossEntropyLoss) adds label smoothing, class weights
+//! and an ignore index to the plain function.
+//!
+//! ## Data
+//!
+//! A [`Dataset`](data::Dataset) is anything indexable that can write one item
+//! into a slice. A [`DataLoader`](data::DataLoader) turns it into shuffled
+//! batches and can place them on a device. Items go into one buffer per batch,
+//! so batching 60,000 images does not allocate 60,000 tensors.
+//!
+//! ```
+//! use fastnn::prelude::*;
+//!
+//! let inputs = Tensor::randn(&[100, 8]);
+//! let targets = Tensor::from_vec((0..100).map(|i| (i % 3) as f32).collect(), &[100]);
+//! let dataset = TensorDataset::new(&inputs, &targets);
+//!
+//! let loader = DataLoader::new(&dataset, 32).shuffle(true);
+//! for batch in loader.iter() {
+//! let labels = batch.labels(); // targets as class ids
+//! assert_eq!(batch.inputs.dim(0), labels.len());
+//! }
+//! ```
+//!
+//! [`Mnist::load`](data::Mnist::load) downloads the digits once and caches them.
+//! The [`data`] page shows a dataset written from scratch.
+//!
+//! ## Checkpoints
+//!
+//! [`save`](serialize::save) writes the weights, which is all a finished model
+//! needs. A run that has to survive a crash needs more: Adam's moments and step
+//! count drive its bias correction, and restored without them it restarts at
+//! step 1 with an oversized first update.
+//! [`save_training`](serialize::save_training) writes the weights, the optimizer
+//! state and the step together, and [`load_training`](serialize::load_training)
+//! refuses a plain weights file rather than silently resetting the optimizer.
+//!
+//! ```
+//! # use fastnn::prelude::*;
+//! # let dir = std::env::temp_dir().join("fastnn-doc-resume");
+//! # std::fs::create_dir_all(&dir)?;
+//! # let path = dir.join("run.fdl");
+//! # let _ = std::fs::remove_file(&path);
+//! # let model = Sequential::new().add(Linear::new(4, 2));
+//! # let mut opt = Adam::new(model.parameters(), 1e-3);
+//! # let total = 500;
+//! let mut step = load_training(&model, &mut opt, &path).unwrap_or(0);
+//!
+//! while step < total {
+//! // one training step
+//! step += 1;
+//! if step % 500 == 0 {
+//! save_training(&model, &opt, step, &path)?;
+//! }
+//! }
+//! # Ok::<(), fastnn::Error>(())
+//! ```
+//!
+//! [`save_safetensors`](serialize::save_safetensors) and
+//! [`load_safetensors`](serialize::load_safetensors) exchange weights with other
+//! tools. F16 and BF16 files load and are widened to `f32`.
//!
-//! Tensor maths panics on shape and device mistakes. [`Result`] is for I/O,
-//! dataset downloads, and CUDA.
+//! ## GPU
//!
-//! Everything starts on the CPU. Move the model with
-//! [`Module::to_device`](nn::Module::to_device) and the batches with
-//! [`DataLoader::to_device`](data::DataLoader::to_device).
+//! Everything starts on the CPU. Move the model and the loader, and the training
+//! loop stays the same. Mixing devices panics instead of copying behind your back.
//!
//! ```no_run
//! # use fastnn::prelude::*;
//! # let model = Sequential::new();
//! # let dataset: fastnn::data::TensorDataset = unimplemented!();
-//! let device = Device::best();
+//! let device = Device::best(); // the first GPU, else the CPU
//! model.to_device(device);
-//! let loader = DataLoader::new(&dataset, 64).to_device(device);
+//! let loader = DataLoader::new(&dataset, 128).to_device(device);
//! ```
+//!
+//! Matmul goes through cuBLAS and everything else through the kernels in
+//! `cuda/kernels.cu`, each checked against the CPU path by the parity tests. The
+//! kernels use fast math, so GPU and CPU results differ in the last few digits.
+//!
+//! ## Generation
+//!
+//! A causal [`TransformerStack`](nn::TransformerStack) decodes through a
+//! [`StackCache`](nn::StackCache), so each new token attends to the whole prefix
+//! without recomputing it. [`Sampler`](nn::Sampler) turns logits into a token,
+//! and [`BeamSearch`](nn::BeamSearch) finds the most probable sequence instead.
+//!
+//! ```
+//! use fastnn::prelude::*;
+//!
+//! let (vocab, width) = (50, 32);
+//! let tokens = Embedding::new(vocab, width);
+//! let positions = Embedding::new(64, width);
+//! let stack = TransformerStack::causal(width, 4, 64, 2, 0.0);
+//! let head = Linear::new(width, vocab);
+//! let sampler = Sampler::new().temperature(0.8).top_k(10);
+//!
+//! let mut ids = vec![1];
+//! let mut cache = stack.new_cache();
+//! no_grad(|| {
+//! for _ in 0..5 {
+//! let last = *ids.last().unwrap();
+//! let x = tokens.lookup(&[last]).add(&positions.lookup(&[cache.len()]));
+//! let hidden = stack.forward_cached(&x.reshape(&[1, 1, -1]), &mut cache);
+//! ids.push(sampler.sample(&head.forward(&hidden)));
+//! }
+//! });
+//! assert_eq!(ids.len(), 6);
+//! ```
+//!
+//! Sampling draws from the thread's random source, so
+//! [`manual_seed`](rng::manual_seed) makes a generation reproducible.
+//!
+//! ## Debugging
+//!
+//! One non-finite gradient poisons the weights, and by the time the loss prints
+//! NaN the op at fault is long gone. [`detect_anomaly`](autograd::detect_anomaly)
+//! checks every gradient as it is produced and panics at the first bad one,
+//! naming the op:
+//!
+//! ```should_panic
+//! # use fastnn::prelude::*;
+//! let w = Param::new(Tensor::from_vec(vec![0.0], &[1]));
+//! detect_anomaly(|| w.tensor().log().sum().backward());
+//! // panics: anomaly: Log produced inf at element 0 of [1] in the gradient for input 0
+//! ```
+//!
+//! It reads every gradient, so keep it for debugging. The cheap guard for a
+//! healthy loop is
+//! [`gradients_are_finite`](optim::Optimizer::gradients_are_finite):
+//!
+//! ```
+//! # use fastnn::prelude::*;
+//! # let model = Linear::new(4, 2);
+//! # let mut opt = Adam::new(model.parameters(), 1e-3);
+//! if !opt.gradients_are_finite() {
+//! opt.zero_grad(); // skip this batch instead of stepping into NaN
+//! }
+//! ```
+//!
+//! Shape and device mistakes panic with a message naming both shapes, since they
+//! are bugs in the calling code. Where a shape comes from outside your code, a
+//! config file or an upload, the `try_` variants return an [`Error`] instead:
+//!
+//! ```
+//! # use fastnn::tensor::Tensor;
+//! let a = Tensor::randn(&[2, 3]);
+//! assert!(a.try_matmul(&Tensor::randn(&[4, 4])).is_err());
+//! ```
+//!
+//! # Tensors
+//!
+//! A [`Tensor`](tensor::Tensor) is an immutable `f32` array on the CPU or a GPU.
+//! Ops return new tensors and broadcast the way NumPy does.
+//!
+//! ```
+//! use fastnn::tensor::Tensor;
+//!
+//! let a = Tensor::from_vec(vec![1.0, 2.0, 3.0, 4.0, 5.0, 6.0], &[2, 3]);
+//! let bias = Tensor::from_vec(vec![10.0, 20.0, 30.0], &[3]);
+//!
+//! let shifted = a.add(&bias); // [2, 3] + [3] broadcasts over the rows
+//! assert_eq!(shifted.to_vec(), vec![11.0, 22.0, 33.0, 14.0, 25.0, 36.0]);
+//!
+//! let gram = a.matmul(&a.transpose()); // [2, 3] x [3, 2]
+//! assert_eq!(gram.shape(), &[2, 2]);
+//!
+//! assert_eq!(a.sum_axis(1).to_vec(), vec![6.0, 15.0]);
+//! assert_eq!(a.argmax(1), vec![2, 2]);
+//! assert_eq!(a.narrow(0, 1, 1).to_vec(), vec![4.0, 5.0, 6.0]);
+//! assert_eq!(a.reshape(&[3, -1]).shape(), &[3, 2]);
+//! ```
+//!
+//! [`Tensor::zeros`](tensor::Tensor::zeros), [`ones`](tensor::Tensor::ones),
+//! [`randn`](tensor::Tensor::randn), [`arange`](tensor::Tensor::arange) and
+//! [`eye`](tensor::Tensor::eye) create tensors, and the Kaiming and Xavier
+//! initialisers are there for weights. [`to`](tensor::Tensor::to) moves a tensor
+//! between devices. The [`tensor::ops`] page lists every operation by kind.
+//!
+//! # Autograd
+//!
+//! A tensor made by a differentiable op carries a node: the rule that made it and
+//! the tensors it consumed. `backward()` walks those nodes and leaves each
+//! weight's gradient in its [`Param`](nn::Param). A tensor with no node is plain
+//! data, so there is no `requires_grad` flag and no tape. Drop the loss and the
+//! graph is freed with it.
+//!
+//! ```
+//! use fastnn::prelude::*;
+//!
+//! let w = Param::new(Tensor::from_vec(vec![1.0, 2.0], &[2]));
+//! let x = Tensor::from_vec(vec![3.0, 4.0], &[2]);
+//!
+//! let loss = w.tensor().mul(&x).sum(); // 1*3 + 2*4
+//! loss.backward();
+//!
+//! assert_eq!(w.grad().unwrap().to_vec(), vec![3.0, 4.0]);
+//! ```
+//!
+//! Wrap inference in [`no_grad`](autograd::no_grad) and no graph is built:
+//!
+//! ```
+//! # use fastnn::prelude::*;
+//! # let w = Param::new(Tensor::randn(&[2]));
+//! let y = no_grad(|| w.tensor().exp());
+//! assert!(y.grad_fn().is_none());
+//! ```
+//!
+//! Every op is two small functions: the forward in `tensor/ops/` and its rule in
+//! [`autograd::ops`], in files with the same names. The rule returns gradients in
+//! input order and saves only detached tensors, and `tests/gradcheck.rs` checks
+//! it against central finite differences of its own forward. Adding an op is
+//! adding those two functions and a test case.
+//!
+//! # Feature flags
+//!
+//! - `cuda` compiles `cuda/kernels.cu` with `nvcc` and links the CUDA runtime,
+//! cuBLAS and cuRAND. It needs a CUDA toolkit and targets GPUs from Turing to
+//! Hopper (`sm_75` to `sm_90`). It is off by default. Without it every op runs
+//! on the CPU and [`Device::cuda`](tensor::Device::cuda) returns an error.
+//!
+//! These docs are built without `cuda`, since docs.rs has no CUDA toolkit.
+//!
+//! # Platform support
+//!
+//! FastNN needs Rust 1.87 or newer.
+//!
+//! | Platform | CPU | CUDA |
+//! |---|---|---|
+//! | Linux x86_64 | Tested in CI | Built in CI, parity tested on real hardware |
+//! | Linux ARM64 | Built for releases | Not supported |
+//! | macOS (Intel, Apple Silicon) | Tested in CI | Not available |
+//! | Windows x86_64 | Tested in CI | Should build, not tested |
+//!
+//! # Modules
+//!
+//! - [`tensor`] is the array type, its ops and devices.
+//! - [`autograd`] is the graph and the backward rules, one file per op category.
+//! - [`nn`] is layers, losses, sampling and beam search.
+//! - [`optim`] is optimizers, schedules and gradient clipping.
+//! - [`data`] is datasets, batching and MNIST.
+//! - [`serialize`] is checkpoints and safetensors.
+//! - [`cuda`] is GPU memory and the kernel bindings.
pub mod autograd;
pub mod cuda;
diff --git a/src/nn/linear.rs b/src/nn/linear.rs
index 9238edf..5673e26 100644
--- a/src/nn/linear.rs
+++ b/src/nn/linear.rs
@@ -6,6 +6,14 @@ use super::module::Module;
use super::param::Param;
/// `y = x · Wᵀ + b` over the last dimension, any number of leading dimensions.
+///
+/// ```
+/// use fastnn::prelude::*;
+///
+/// let layer = Linear::new(4, 2);
+/// let y = layer.forward(&Tensor::randn(&[8, 4]));
+/// assert_eq!(y.shape(), &[8, 2]);
+/// ```
pub struct Linear {
pub weight: Param,
pub bias: Option,
diff --git a/src/nn/mod.rs b/src/nn/mod.rs
index fb259ae..f818283 100644
--- a/src/nn/mod.rs
+++ b/src/nn/mod.rs
@@ -1,5 +1,34 @@
//! Layers, losses and decoding helpers. Everything implements [`Module`], and a
//! layer's weights are shared [`Param`] handles so an optimizer can hold them too.
+//!
+//! ```
+//! use fastnn::prelude::*;
+//!
+//! let cnn = Sequential::new()
+//! .add(Conv2d::new(1, 8, 3, 1, 1))
+//! .add(ReLU)
+//! .add(MaxPool2d::new(2))
+//! .add(Flatten::new())
+//! .add(Linear::new(8 * 14 * 14, 10));
+//!
+//! let logits = cnn.forward(&Tensor::randn(&[4, 1, 28, 28]));
+//! assert_eq!(logits.shape(), &[4, 10]);
+//! ```
+//!
+//! - Layers: [`Linear`], [`Conv1d`], [`Conv2d`], [`ConvTranspose1d`],
+//! [`ConvTranspose2d`], [`MaxPool2d`], [`AvgPool2d`], [`AdaptiveAvgPool2d`],
+//! [`BatchNorm2d`], [`LayerNorm`], [`RMSNorm`], [`Dropout`], [`Embedding`],
+//! [`PositionalEncoding`], [`LSTM`] and [`GRU`].
+//! - Transformers: [`MultiHeadAttention`], [`TransformerStack`] as an encoder or a
+//! causal decoder, [`TransformerDecoder`] with cross-attention, and the
+//! encoder-decoder [`Transformer`].
+//! - Generation: [`KvCache`] and [`StackCache`] for incremental decoding,
+//! [`Sampler`] for temperature, top-k and top-p, and [`BeamSearch`].
+//! - Losses: [`cross_entropy`], [`mse`], [`bce_with_logits`], [`huber`],
+//! [`kl_divergence`], [`dice`], [`triplet_margin`], [`info_nce`] and the rest of
+//! [`loss`] and [`metric_losses`]. [`CrossEntropyLoss`] adds label smoothing,
+//! class weights and an ignore index.
+//! - Plumbing: [`Module`], [`Sequential`], [`Param`] and [`Buffer`].
pub mod activation;
pub mod attention;
diff --git a/src/optim/mod.rs b/src/optim/mod.rs
index 0f1c5d6..d3f634e 100644
--- a/src/optim/mod.rs
+++ b/src/optim/mod.rs
@@ -1,18 +1,35 @@
//! Optimizers and learning-rate schedules.
//!
//! An optimizer owns shared [`Param`] handles, so `step()` needs no model borrow.
+//! A [`LrSchedule`] maps the step to a rate, and [`Optimizer::set_lr`] applies it.
//!
//! ```
//! use fastnn::prelude::*;
//! # let model = Sequential::new().add(Linear::new(4, 2));
//! # let x = Tensor::randn(&[3, 4]);
//! let mut opt = Adam::new(model.parameters(), 1e-3);
+//! let schedule = Warmup::new(CosineAnnealing::new(1e-3, 10_000), 500);
//!
-//! let loss = cross_entropy(&model.forward(&x), &[0, 1, 0]);
-//! opt.zero_grad();
-//! loss.backward();
-//! opt.step();
+//! for step in 0..3 {
+//! opt.set_lr(schedule.lr_at(step));
+//! let loss = cross_entropy(&model.forward(&x), &[0, 1, 0]);
+//!
+//! opt.zero_grad();
+//! loss.backward();
+//! clip_grad_norm(opt.parameters(), 1.0);
+//! opt.step();
+//! }
//! ```
+//!
+//! - Optimizers: [`SGD`], [`Adam`], [`AdamW`], [`RMSprop`], [`Adagrad`],
+//! [`Adadelta`], [`RAdam`] and [`Lion`].
+//! - Wrappers: [`Lookahead`] around any optimizer, and [`Ema`] for averaged
+//! weights to evaluate and ship.
+//! - Schedules: [`Constant`], [`StepDecay`], [`CosineAnnealing`], [`OneCycle`],
+//! and [`Warmup`] around any of them.
+//! - Clipping: [`clip_grad_norm`] and [`clip_grad_value`].
+//! - [`OptimizerState`] is what [`save_training`](crate::serialize::save_training)
+//! stores, so a resumed run keeps its moments and step count.
pub mod adagrad;
pub mod adam;
diff --git a/src/serialize/mod.rs b/src/serialize/mod.rs
index 2c0bffe..60e0601 100644
--- a/src/serialize/mod.rs
+++ b/src/serialize/mod.rs
@@ -1,5 +1,29 @@
//! Checkpoints: `.fdl` weights, `.fdl` training state, safetensors, and the
//! 16-bit float conversions safetensors needs.
+//!
+//! - [`save`] and [`load`] move a model's weights to and from a file. Shapes must
+//! match, and a tensor that moved is an error, not a silent skip.
+//! - [`save_training`] and [`load_training`] add the optimizer state and the step,
+//! which is what makes a run resumable.
+//! - [`save_safetensors`] and [`load_safetensors`] speak the format the rest of
+//! the ecosystem uses. F16 and BF16 load and are widened to `f32`, and
+//! [`load_safetensors_renamed`] maps foreign names onto yours and reports what
+//! matched.
+//!
+//! ```
+//! # use fastnn::prelude::*;
+//! # let path = std::env::temp_dir().join("fastnn-doc-save.fdl");
+//! let model = Sequential::new().add(Linear::new(4, 2));
+//! save(&model, &path)?;
+//!
+//! let fresh = Sequential::new().add(Linear::new(4, 2));
+//! load(&fresh, &path)?;
+//! assert_eq!(
+//! fresh.parameters()[0].value().to_vec(),
+//! model.parameters()[0].value().to_vec(),
+//! );
+//! # Ok::<(), fastnn::Error>(())
+//! ```
pub mod checkpoint;
pub mod half;
diff --git a/src/tensor/mod.rs b/src/tensor/mod.rs
index 88de50d..941bab2 100644
--- a/src/tensor/mod.rs
+++ b/src/tensor/mod.rs
@@ -1,4 +1,32 @@
//! Tensors: shape, storage and the link into the autograd graph.
+//!
+//! A [`Tensor`] is an immutable `f32` array on the CPU or a GPU. Ops return new
+//! tensors and broadcast the way NumPy does. A shape an op cannot handle panics
+//! with a message naming both shapes; the `try_` variants return an error instead.
+//!
+//! ```
+//! use fastnn::tensor::Tensor;
+//!
+//! let a = Tensor::from_vec(vec![1.0, 2.0, 3.0, 4.0, 5.0, 6.0], &[2, 3]);
+//! let bias = Tensor::from_vec(vec![10.0, 20.0, 30.0], &[3]);
+//!
+//! let shifted = a.add(&bias); // [2, 3] + [3] broadcasts over the rows
+//! assert_eq!(shifted.to_vec(), vec![11.0, 22.0, 33.0, 14.0, 25.0, 36.0]);
+//!
+//! let gram = a.matmul(&a.transpose()); // [2, 3] x [3, 2]
+//! assert_eq!(gram.shape(), &[2, 2]);
+//!
+//! assert_eq!(a.sum().item(), 21.0);
+//! assert_eq!(a.reshape(&[3, -1]).shape(), &[3, 2]);
+//! ```
+//!
+//! - Creation: [`Tensor::from_vec`], [`Tensor::zeros`], [`Tensor::ones`],
+//! [`Tensor::randn`], [`Tensor::arange`], [`Tensor::eye`] and the Kaiming and
+//! Xavier initialisers.
+//! - [`ops`] holds every operation, grouped by kind: arithmetic, unary, activations,
+//! matmul, reductions, views, indexing, convolution, pooling and normalization.
+//! - [`Device`] is CPU or a numbered GPU, and [`Tensor::to`] moves a tensor between them.
+//! - [`shape`] has strides and broadcasting, [`storage`] has the bytes.
mod checked;
mod core;